A Best Match Is Not a Twin: What Feature Similarity Between State Space Models and Transformers Certifies, Why the Null and the Shared Inputs Decide the Verdict, and the Controls That Would Show Two Architectures Learned the Same Thing
Abstract
Life of Research
Selective state space models such as Mamba compress the past into a fixed-size state, while Transformers attend over the whole context, and a growing set of studies asks whether the two learn the same internal features. A 2026 study reports that 99.98% of a Mamba model's sparse-autoencoder features have a strong Transformer counterpart and reads this as support for the universality hypothesis. In this analysis the author reviews and synthesises published results to show that such verdicts are set less by the models than by three choices the measurement makes: the reference point a score is judged against, the inputs the two models share, and the instrument that extracts features. The author derives the expected Jaccard similarity of two binary features that share nothing and shows that the study's reported band, 0.234 to 0.411 for every feature's best match, is what unrelated features would score if they fired on roughly a quarter to three fifths of tokens; firing rates were not reported, so this cannot be checked. Against same-architecture skylines, the strongest design supports a narrower claim than universality: features recur across the two families nearly as well as across random seeds, most strongly for token-level features, while the documented differences sit in context mixing and recurrent state, which residual-stream dictionaries do not measure. Sixteen published findings are consolidated in a table, a seven-step procedure licenses a convergence claim at one of four levels, and five studies are proposed that would settle the open part.
About the author
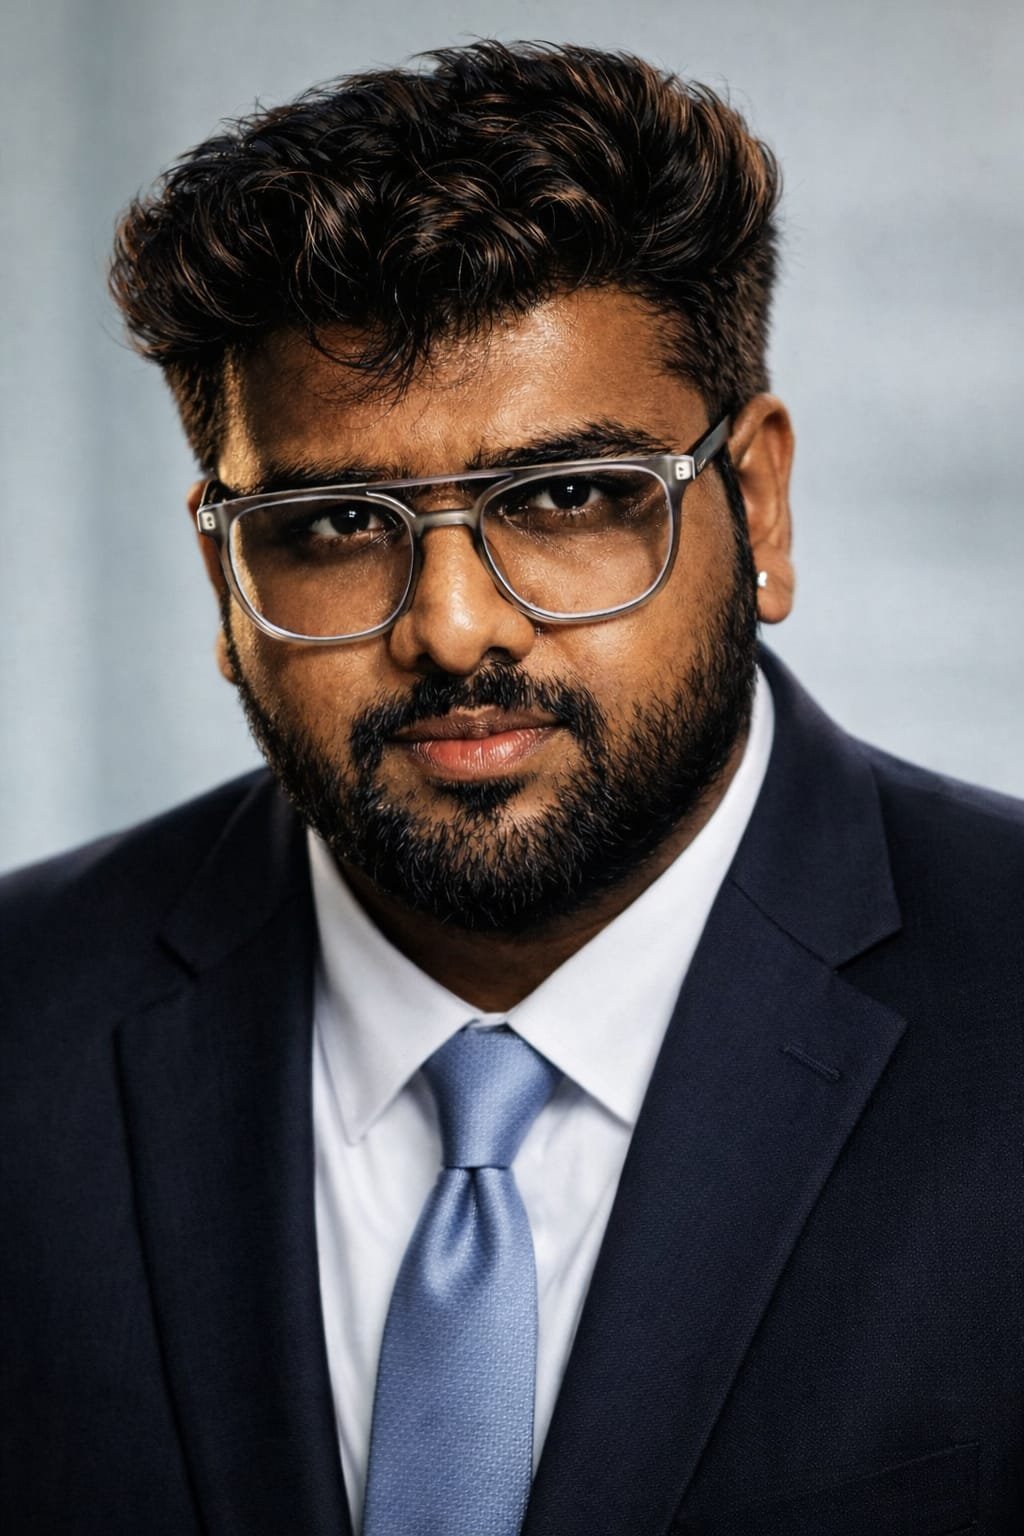
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 114 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "A Best Match Is Not a Twin"?
Pranay Mahendrakar wrote "A Best Match Is Not a Twin: What Feature Similarity Between State Space Models and Transformers Certifies, Why the Null and the Shared Inputs Decide the Verdict, and the Controls That Would Show Two Architectures Learned the Same Thing", published 26 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "A Best Match Is Not a Twin" free to read?
Yes. "A Best Match Is Not a Twin" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23652519. There is no paywall and no account required.
How do I cite "A Best Match Is Not a Twin"?
Cite the DOI: Mahendrakar, P. (2026). A Best Match Is Not a Twin: What Feature Similarity Between State Space Models and Transformers Certifies, Why the Null and the Shared Inputs Decide the Verdict, and the Controls That Would Show Two Architectures Learned the Same Thing. Zenodo. https://doi.org/10.5281/zenodo.23652519 A BibTeX entry is provided on this page.