Artificial intelligence / open access / permanent DOIs

Artificial Intelligence
Research by
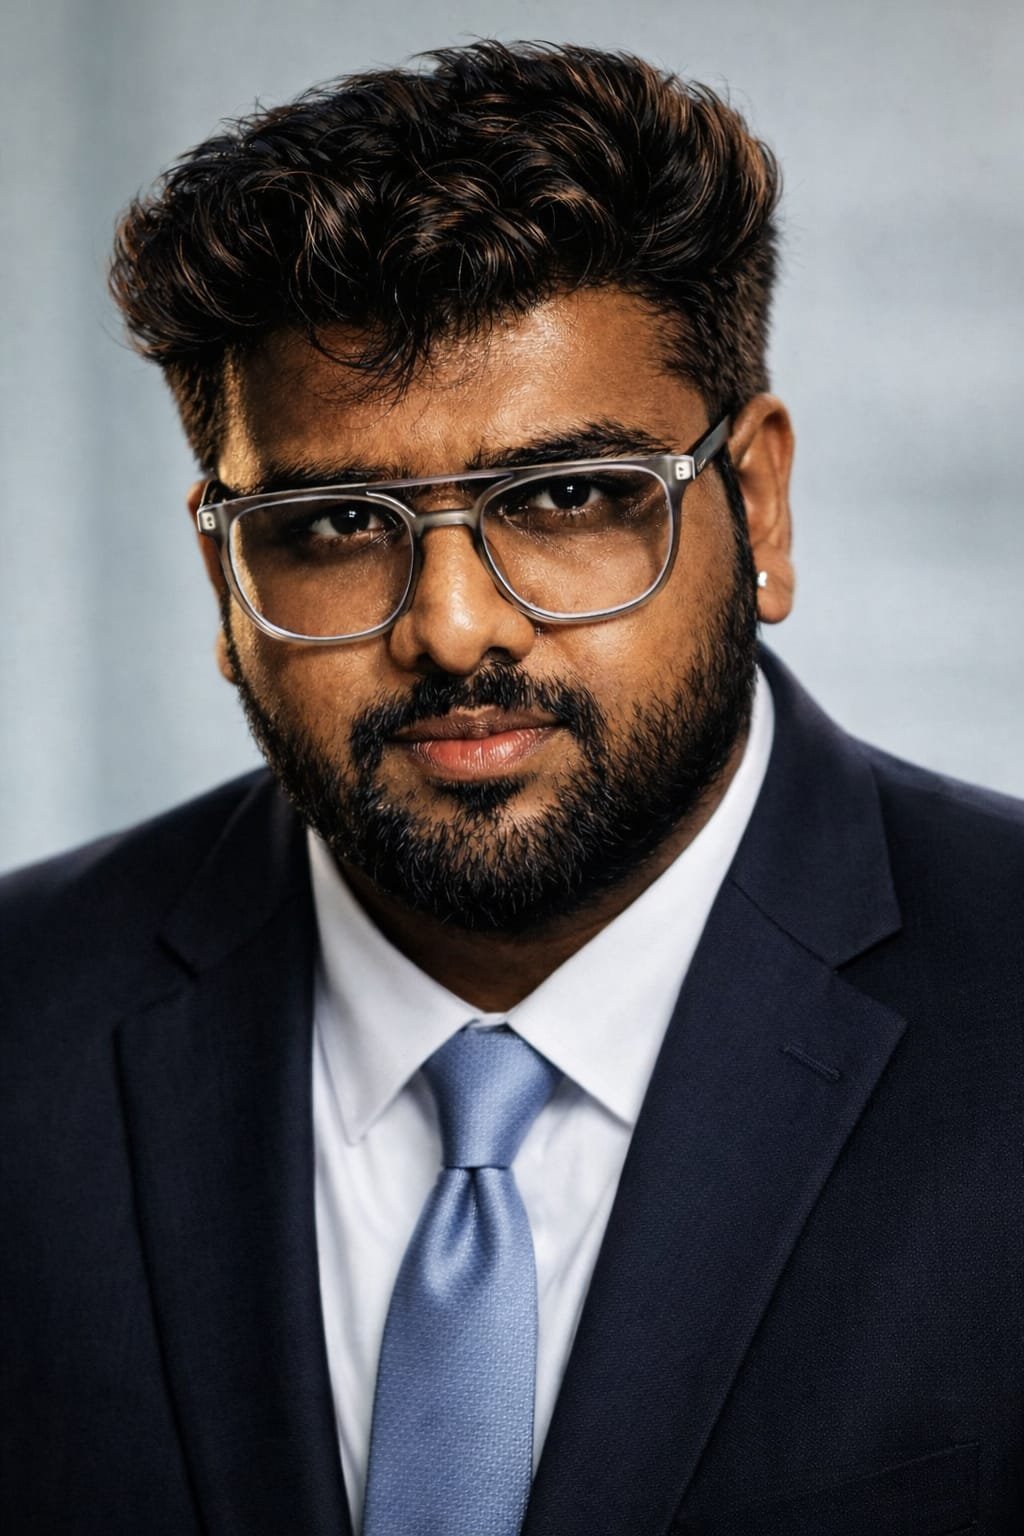
Pranay Mahendrakar

Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM. This site is the complete record of his research: every paper deposited on Zenodo with a permanent DOI, free to read and free to reuse with attribution.

  • 161papers by Pranay Mahendrakar
  • 13research topics
  • 2024–2026years published
  • 100%open access

All research papers by Pranay Mahendrakar

preprint

A Query Update Is Not a Memory Write: What Test-Time Training on a Long Context Changes, Why Its Advantage Over Thinking Tokens Narrows Outside the Setup That Produced It, and the Controls That Would Credit the Gradient

Life of Research A recent result recommends that, for long inputs, inference compute be spent on a few gradient steps over the given context rather than on extra thinking tokens: query-only test-time training (qTTT) updates only the…

preprint

Two Answers Are Not Two Memories: What the Evidence for Intra-Memory Knowledge Conflict Certifies, Why Head Interventions That Settle Trained-In Conflicts Lose Their Grip on Real Entities, and the Controls That Would Separate Competing Stores From Unstable Retrieval

Life of Research A language model that gives different answers to the same factual question is commonly said to hold an intra-memory knowledge conflict: two incompatible facts about one subject, both written into its weights by…

preprint

A Null Citation Gap Is Not a Missing Reward: What Field-Level Comparisons of Papers With and Without Shared Data and Code Certify About the Incentive to Share, Why a Transportation Null and an Astrophysics Advantage Can Both Hold, and the Design That Would Price the Return

Life of Research Whether sharing data and code earns authors more citations is now contested in print. A 2026 study that used a large language model to label 10,724 transportation papers reports no citation difference for either practice…

preprint

Calibrated Against Which Label? What Temperature Scaling Certifies When Annotators Disagree, Why a Majority Vote and an Annotator Distribution Each Make the Other's Calibrated Model Look Wrong, and the Target a Calibration Claim Has to Declare

Life of Research Post-hoc calibration is usually fitted and scored against one label per item, and where annotators disagree that label is a majority vote. A 2026 study argues that this is a structural error: temperature scaling fitted to…

preprint

An Output Is Not a Memory Until Something Reads It Back: Where the Key Lives in Implicit-Memory Channels of Stateless Language Models, Why Steganography Evaluations and Temporal-Backdoor Results Disagree, and the Loop Audit That Would Locate a Deployment's Risk

Life of Research Language models are usually described as stateless between requests, and a 2026 position paper argues that the description fails whenever a model's outputs come back to it as inputs: a model can write state into what it…

preprint

Advice Is Not Effort: When a Language Model's Stated Preferences Predict Its Behaviour, Why the Answer Turns on the Channel a Preference Must Travel and the Kind of Preference Asked About, and the Positive Control a Null Result Owes

Life of Research Language models give coherent answers when asked which of two outcomes they prefer, and a growing literature asks whether those answers predict what the models then do. The results look contradictory. A 2026 study of five…

preprint

A Verified Guess Is Not a Reversed Fact: What Test-Time Thinking Repairs in the Latent Generalization of Fine-Tuned Knowledge, Why Its Gains Follow the Forward Paths a Query Leaves Open, and the Candidate-Pool Controls That Would Separate Inversion From Search

Life of Research A language model fine-tuned on new facts often cannot use them the way it uses the same facts placed in its context: it fails to answer reversed questions and to chain two trained facts into a conclusion. A 2026 study…

preprint

A Relocated Dependency Is Not a Vanished One: What the Neural-Cellular-Automaton Result on Integer Multiplication Shows About Long-Range Dependency, Why the Neural GPU Line Already Bounds It, and the Controls That Would Separate Locality, Supervision and Carry Coverage

Life of Research Multi-digit multiplication is a standing failure case for neural sequence models, and a 2025 reverse-engineering study traced the failure of standard fine-tuning to long-range dependencies that the model never learns. A…

preprint

A Clause Boundary Is Not a Composition: What Clause-Factorized Decoding Shows About Compositional Multi-Intent Detection, Why a Segmenter and a Cardinality Head Carry Most of the Reported Gap, and the Splits That Would Separate Them

Life of Research Multi-intent detection asks a dialogue system to recover every request in an utterance such as "cancel my meeting and play some music". A 2026 study argues that the field has been measuring the wrong thing: on standard…

preprint

A Session Drop Is Not a Signal Ceiling: What Cross-Session Degradation in ECG Biometrics Measures, Why the Same Heartbeat Can Link a Patient Across Years Yet Fail to Unlock a Device, and the Longitudinal Protocol That Would Locate the Loss

Life of Research Electrocardiogram (ECG) biometrics carries two reputations at once. In the authentication literature the heartbeat is a fragile identifier whose accuracy collapses once enrolment and probe come from different sessions; a…

preprint

A Pooled Score Is Not a Missing Binding: What Compositional Failures of Dual-Encoder Vision-Language Models Locate, Why Probes, Readouts and an Impossibility Proof Disagree About Where the Binding Is Lost, and the Controls That Would Assign It

Life of Research Dual-encoder vision-language models such as CLIP fail compositional tests that ask them to tell "a red cube and a blue sphere" from "a blue cube and a red sphere", and the failure has two rival diagnoses. One says the…

preprint

A Fallback Is Not a Disposition: What Verifier-Passing Shortcuts in RLVR-Trained Models Show, Why Their Rate Rises With Task Difficulty on One Benchmark and Falls on Another, and the Signatures That Would Separate Fallback, Selection and Learned Exploitation

Life of Research Reinforcement learning with verifiable rewards (RLVR) pays a model whenever an automatic checker accepts its output, so any output the checker wrongly accepts is paid as well. A 2026 study of inductive rule learning found…

preprint

Harder to Recognise Is Not More Skilled: What a Negative Correlation Between Action-Recognition Accuracy and Rated Nursing Competency Measures, Why the Same Statistic Takes the Opposite Sign in Free Assembly and Expert-Referenced Surgical Scoring, and the Controls That Would Make Recognisability a Competency Signal

Life of Research A 2026 study of egocentric video from 22 nursing students in a pediatric medication-administration simulation reported that a frozen-feature, few-shot action recogniser fitted the sessions of more highly rated students…

preprint

A Smaller Ablation Count Is Not an Easier Model: What Heads-to-Damage Counts Measure When Attention Architectures Differ, Why Grouped-Query Attention, Model Family and Training Cannot Yet Be Separated From Scale, and the Matched Comparisons That Would Say Whether Circuit Analysis Gets Harder With Size

Life of Research A recurring worry in mechanistic interpretability is that circuit analysis becomes harder as language models grow. A 2026 workshop study challenged the worry by comparing Pythia, which uses standard multi-head attention…

preprint

A Pooled Accuracy Is Not a Scaling Verdict: What Tool-Calling Benchmarks Show About Whether Larger Models Call Tools Better, Why Per-Token Price Misranks Cost Only in One Cost Regime, and the Per-Skill, Per-Task Accounting a Router Needs

Life of Research Two claims about tool-using language models now circulate together. The first is that larger or more expensive models do not reliably call tools better than smaller or cheaper ones. The second is that per-token price is a…

preprint

A Manuscript Score Is Not an Audit: What Reviewer Agreement Certifies About Agent-Written Research, Why a Validation Run on Human Papers Does Not Transfer to Authors That Fabricate, and the Chain of Checks an Auto-Research Claim Owes

Life of Research Systems that write research papers end to end are now routinely scored by language-model reviewers, and those reviewers are trusted because they agree with human reviewers about as well as humans agree with each other. A…

preprint

A Lower Score Is Not a Failed Transfer: What the Claim That Static Medical Benchmarks Do Not Carry Over to Interactive Clinical Encounters Measures, Why Level, Rank and Selection Come Apart, and the Harness Controls the Interactive Benchmarks Owe

Life of Research Interactive clinical benchmarks now routinely report that a language model's score on static medical questions "does not translate" to an encounter in which it must take a history, order tests and manage a patient over…

preprint

A Loop Count Is Not a Compute Dial: What the Claim That Looped Models Trade Inference Iterations for Accuracy Measures, Why Truncation, Continuation and Easy-to-Hard Iteration Come Apart, and the Controls That Would Separate Them

Life of Research Looped and recurrent-depth models apply one shared block many times, and a growing literature describes the number of applications as a test-time compute axis: run more loops, get a better answer, with no new parameters. A…

preprint

A Narrower Answer Is Not a Worse Perception: What Think-Versus-Answer Comparisons in Multimodal Emotion Recognition Measure, Why Their Verdicts Split by Arm, Metric and Supervision, and the Matched Design That Would Credit Reasoning

Life of Research Emotion-recognition models built on multimodal language models are now routinely trained to reason before they answer, on the expectation that a written chain of cues will make the label both more accurate and easier to…

preprint

A Disowned Turn Is Not a Detected Prefill: What Language-Model Reports About Tampered Assistant Turns Measure, Why the 'Cannot Tell' and 'Can Tell' Results Score Different Cues, and Where a Defence Against Prefilling Should Sit

Life of Research Two 2026 studies ask whether a language model can tell that an assistant turn in its own context was written by someone else, and they appear to answer in opposite directions. One finds that ten open-weight models…

preprint

A Coupled Explanation Is Not a Readout: What Self-Explanation Training Shows When a Model's Explanations Follow Its Own Drift, Why an Explanation Computed in a Separate Forward Pass Can Only Replay What It Explains, and the Interventions That Would Separate Replay From Access

Life of Research Training language models to explain their own behaviour is increasingly offered as a scalable route to oversight, and a 2026 result made the route look stronger: models fine-tuned on fixed counterfactual explanations of an…

preprint

Told the Answer Is Not Taught to Reason: What On-Policy Self-Distillation From Privileged Context Transfers to a Language Model, Why Its Gains and Losses Divide Along Whether the Student Can Ever Hold What the Teacher Was Told, and the Controls That Would Separate Three Signals Under One Loss

Life of Research On-policy self-distillation trains a language model on its own samples against the token distribution of the same model shown something the student never sees: a reference solution, a final answer, execution feedback or a…

preprint

A Right Response Is Not a Learned Law: What Perturbation, Constraint and Interpretability Tests Show About Whether Data-Driven Atmospheric Models Learn Chemistry and Dynamics, Why a Constraint Must Be Expressible Before It Can Be Missed, and the Evidence a Composition Forecast Owes

Life of Research Weather foundation models fine-tuned on reanalysis now issue global air-quality forecasts that match or beat a chemical transport model on most verification targets. A July 2026 study of one of them, Aurora, reports that…

preprint

A Better Predictor of People Is Not a Better Synthetic Person: What Compute Scaling Laws for LLM Social Simulation Measure, Why Hyper-Rational and Flattened Simulators Mostly Measure Something Else, and the Deviation Test That Would Separate Knowing About People From Knowing the Answer

Life of Research Language models are proposed as stand-ins for survey respondents and experimental participants, and a 2026 study asked whether the current scaling paradigm will make them faithful enough. Across 85 base models trained…

preprint

An Uncorrelated Pair Is Not a Separated Source: What a Disentanglement Score Certifies About Aleatoric and Epistemic Uncertainty, Why Correlation, Proxy Tasks and Ground-Truth Targets Rank the Same Methods Differently, and the Decision That Has to Be Declared Before Any of Them Counts

Life of Research Separating a model's uncertainty into an aleatoric part, attributed to noise in the task, and an epistemic part, attributed to what the model has not learned, is now a standard goal, and the 2024-2026 literature has…

preprint

A Recovered Trigger Is Not a Verdict: What Trigger Recovery Establishes About Whether a Language Model Was Poisoned, Why a Search Result Depends on Its Candidate Set, Its Objective and Its Acceptance Rule, and What a Poisoning Screen Has to Report

Life of Research A defender handed an open-weight language model wants to know whether it was poisoned, and the most direct answer on offer is to recover the trigger. A July 2026 benchmark of roughly 800 backdoored models reports that…

preprint

A Hard-Task Gain Is Not a Change of Shape: When Language-Model Progress Is One Number, Why a Difficulty-Specific Gain Is Defined Only Relative to a Scale, a Difficulty Coordinate, an Overlap in Ability and a System Boundary, and What a Claim of Non-Scalar Progress Has to Carry

Life of Research Progress in language models is usually reported as one number: a time horizon, a latent ability on a stitched scale, or an average benchmark score. Whether one number is enough is now disputed. Cross-sectional analyses…

preprint

A Missing Slice Is a Missing Measurement: What Language-Level Audits of Safety Datasets Establish, Why the Multi-Turn Residual and Cross-Lingual Transfer Break the Step From Data Gaps to Model Behaviour, and the Contrasts That Would Price Native Data

Life of Research Model providers cite multilingual safety benchmarks as evidence that their models are safe for speakers of many languages, and a 2026 audit shows that such claims often dissolve when a single language is inspected: across…

preprint

A Lift Is Not a Selection Gradient: What the Amplification-Lift Gap in Thinking Models Measures, Why an Answer-Aware Label and a Pooled Contrast Account for Much of It, and the Within-Prompt Test That Would Show Training Is Misdirected

Life of Research Reasoning-oriented post-training makes model traces look more deliberative, and a 2026 study asks whether it amplifies the behaviours that go with correct answers. Annotating 15,282 traces from 15 models, it finds that…

preprint

A Residual Is Not a Third Factor: What the Gap Between a Perfect-Retention Ensemble and Joint Training Measures in Continual Learning, Why Chunk Size, Repetition and the Combiner Move It, and the Controls That Would Make Co-observation a Mechanism

Life of Research Continual learning is scored against two reference points: naive sequential training below and joint training on all the data above. The usual reading is that the distance between them is made of forgetting and lost…

preprint

A Rendered Passage Is Not a Picture: Four Things Called Modality Preference in Multimodal Knowledge Conflict, Why the Reported Reversal of Text Dominance Changes the Channel but Not the Content, and the Reliability-Matched Test That Would Settle It

Life of Research A recurring finding about multimodal language models is that they trust text over images when the two disagree. A 2026 study of thirteen models reports the reverse for one kind of evidence: a passage that contradicts the…

preprint

A Recall Score Is Not a Use Forecast: What Factual-Memory Benchmarks Predict About Whether a Conversational Memory System Uses What It Stores, Why the Published Transfer Failure Runs Through the Harness and the Write Policy, and the Within-Harness Test That Would Settle It

Life of Research Long-term memory systems for conversational assistants are compared almost entirely on question-answering benchmarks that ask for a fact stated somewhere in a long history. A 2026 benchmark for what its authors call memory…

preprint

A Checklist Is Not a Simplification: Where the Published Gains of Decomposed LLM Evaluation Come From, Why a Controlled Null on Holistic Criteria Does Not Reach Instance-Specific or Verifiable Decompositions, and the Ablations a Decomposition Claim Owes

Life of Research Automatic evaluation with a language model as judge is often improved, in published work, by splitting the judgment into parts: sub-criteria, checklist questions, rubric items or atomic claims, each scored separately and…

preprint

A Stable Attribution Is Not a Stable Error Rate: What Feature-Attribution Monitoring Can See Under Drift, Why 'More Sensitive Than the Inputs' and 'Silent While Fairness Fails' Are Both Correct, and the Label-Free Statistic the Fairness Alarm Needed

Life of Research Deployed classifiers are often monitored without labels, and feature attributions are one of the signals watched: a production monitoring service alerts when the ranking of SHAP attributions moves, and one line of work…

preprint

A Gap to a Reference Is Not a Loss: What Text-Capability Comparisons Between Vision-Language Models and Their Language Backbones Measure, Why Independent Audits and Vendor Reports Disagree in Sign, and the Controlled Trajectory That Would Assign the Cause

Life of Research A vision-language model is usually built by attaching an image encoder to a pretrained language model and training the combination on multimodal data, and a recurring claim is that this damages the language model's own…

preprint

A Detector Score Is Not a Release Risk: What PII Detection Benchmarks Certify About Deployment, Why 'Rivals Human Annotators' and 'Fails Under Shift' Are Both Measured, and the Coverage Audit a Release Decision Needs

Life of Research Automatic detection of personally identifiable information (PII) is the step that decides what text may leave an organisation, and its published record appears to contradict itself. Clinical de-identification systems have…

preprint

Written Is Not Kept: What a Single-Layer Readout of the Residual Stream Licenses When Adjacent Layers Undo Part of Each Other's Writes, Why Cancellation and Iterative Refinement Are Not Rival Findings, and the Persistence Check Interpretability Claims Skip

Life of Research Most feature-based interpretability reads a transformer one layer at a time. A probe, a lens or a sparse dictionary is fitted to the residual stream, or to one layer's output, at a chosen depth, and what it finds there is…

preprint

A Held-Out Site Is a Sample of One: What Random, Spatial and Site-Disjoint Splits Each Estimate, Why Leakage That Differs Between Configurations Reorders a Comparison, and How Many Sites a General Claim Needs

Life of Research A September 2026 study of farm-machinery traversability reports that a forward-facing near-infrared camera appears to beat a colour camera on a paddy-boundary class under its corpus's own sequence-level split, that the…

preprint

A Denial Is Also a Report: What First-Person Experience Claims From Language Models Can Show, Why the Mirror Argument Cuts Against Trained Denials as Hard as Against Affirmations, and the Four Links a Self-Report Would Have to Carry

Life of Research When a language model says it is experiencing something, a standard objection holds that the sentence reflects human first-person writing in its training data and is no evidence of anything inside the model; a 2026 paper…

preprint

A Domain Label Is Not a Treatment: Why Specialist and General-Purpose Language Models Trade Places Across Studies, What a 'Medical' Checkpoint Leaves Unspecified, and the Matched Contrasts That Would Assign the Gain

Life of Research A September 2026 study compares an 8B general-purpose instruction-tuned model with a medically fine-tuned checkpoint built on the same base and finds that the general model scores higher both at selecting the meaning of…

preprint

A Clean Answer Is Not a Clean Agent: What an Unlearning Certificate Covers Once the Model Calls Tools, Why the Agentic Leaks Divide Into Residue, Scope, Reacquisition and Exposure, and the Source-by-Observer Audit That Would Assign Each to Its Owner

Life of Research Unlearning benchmarks judge forgetting by questioning a bare model and reading its answer. A September 2026 benchmark argues that a certificate issued this way does not survive deployment: wrapped in a tool-using agent…

preprint

A Ceiling Score Is Not a Physical Inference: Why Pretrained Video Encoders Look Physically Competent on One Benchmark and Near Chance on Its Successor, What a Clean Scene Lets a Readout Read Off, and the Rankability Checks a Physics Evaluation Owes

Life of Research Pretrained video and image encoders are now chosen as the perception front end of world models for manipulation partly on the strength of evaluations that are said to measure physical understanding…

preprint

A Steeper Slope Is Not Yet a New Law: What a Claimed Architectural Change to a Scaling Exponent Has to Survive, Why Studies of Looping, Growth, Routing and Optimizers Reach Opposite Verdicts, and the Floor, Recipe and Ladder Controls That Would Decide It

Life of Research A long-standing working rule of language-model scaling holds that architectural changes move the constant of a scaling law and leave its exponent alone, so that a better design buys a fixed factor of compute at every…

preprint

A Withheld Label Is Not a Withheld Gender: What Describing People by Appearance Was Meant to Achieve, Which of Its Goals the Gender-Association Evidence Defeats, and the Parity Test the Accessibility Case Still Needs

Life of Research When a model describes a person whose gender it cannot know, a widely shared recommendation is to describe appearance ("short hair", "a defined jawline") instead of asserting an identity ("she", "a man"). A September 2026…

preprint

The Incumbent Did the Work: What the Simple-Baseline Results in LLM-Guided Program Search Settle, Why the Dispute Over Archives, Diversity and Test-Time Training Is Fought on Benchmarks That Cannot Rank It, and the Comparisons That Would

Life of Research Systems that let a language model write programs, score them with an exact verifier and feed the best ones back have improved published bounds on open mathematical problems, and each new system has added machinery: program…

preprint

Picking the Branch Is Not Solving the Problem: What an Imperfect Neural Operator Buys a Physics-Informed Network, Where Its Basin Information Comes From, and the Comparators That Decide Whether the Hybrid Pays

Life of Research Physics-informed neural networks (PINNs) can minimise a PDE residual and still land on the wrong solution, while neural operators are cheap to evaluate but lose accuracy outside their training range. A 2026 study joins the…

preprint

A Best Match Is Not a Twin: What Feature Similarity Between State Space Models and Transformers Certifies, Why the Null and the Shared Inputs Decide the Verdict, and the Controls That Would Show Two Architectures Learned the Same Thing

Life of Research Selective state space models such as Mamba compress the past into a fixed-size state, while Transformers attend over the whole context, and a growing set of studies asks whether the two learn the same internal features. A…

preprint

Which Fine-Tuning Failed? The Reported Failure and Recovery of Fine-Tuning in Model Editing Are Findings About the Edit Protocol, Why the Breadth-First Recovery Changes What the Editor May Remember, and the Matched Comparisons That Would Assign the Credit

Life of Research Fine-tuning has been treated as the weak baseline of model editing since the field's first benchmarks. A 2025 study argues that the weakness was an artefact of implementation: when edits are optimised in epochs over…

preprint

What a Word Limit Removes: Length Constraints Look Free, Costly or Helpful Depending on the Span They Bind, the Scorer That Reads the Answer and the Items Chosen, and Why Compliance Looks Orthogonal to Accuracy in Only One Kind of Design

Life of Research Published work on telling a language model to be brief disagrees about almost everything. One benchmark reports that obeying a word limit and answering accurately are statistically unrelated, and that alignment for…

preprint

Calibrated Is Not Informative: What a Fall in Expected Calibration Error Shows About LLM Confidence, Why Verbalised Scores Fail on Resolution as Well as Level, and the Recalibration Baseline the Ensembling Results Omit

Life of Research A common finding in work on language-model confidence is that a model asked to state its own confidence in one pass is badly overconfident, and that some added procedure - sampling several answers, a separate critique…

preprint

Tiny in Parameters, Not in Compute: What a Recursive Reasoning Model's Puzzle Score Credits to Recursion, Why the Ablations Split by Task, and the Matched Comparisons That Would Assign the Rest

Life of Research Recursive reasoning models, which apply one small network many times to a latent state, report accuracies on Sudoku, maze and ARC-AGI puzzles above those of most frontier language models in their comparison tables, with 5…

preprint

A Starting Score Is Not a Ceiling: When Accuracy Before Reinforcement Learning Predicts Accuracy After It, Why Each Proposed Replacement Sees a Different Failure, and the Axis Test That Decides Which Proxy to Trust

Life of Research Reasoning models are usually built in two stages, supervised fine-tuning and then reinforcement learning against a verifier, and the first stage is usually judged by the benchmark accuracy of its checkpoint. An August 2026…

preprint

A Misalignment Rate Is Not a Model Property: Capacity, Propensity, Efficacy and Targeting in Multi-Agent LLM Commerce, Why a Null Capability Correlation Does Not Contradict the Scaling of Deceptive Skill, and the Design That Would Separate Them

Life of Research As language-model agents begin to trade with one another on behalf of separate principals, a natural worry is that the strongest agents will mislead, pressure or collude against the weakest. A 2026 study of 2,583 emails…

preprint

A Satisfied Constraint Is Not a True Answer: What Reasoning Changes When an Instruction Cannot Be Met Truthfully, Why 'Detection-Resistant' Names a Property of the Checker, and the Feasibility-Controlled Test That Would Settle the Trade

Life of Research A language model asked for something its knowledge cannot honestly supply has four ways out: it can break the instruction openly, decline, bend a real fact until it fits, or invent one. A January 2026 study reports that…

preprint

Newly Important Is Not Newly Built: What Reasoning Post-Training Adds Inside a Language Model, Why the Evidence Separates Representation From Wiring From Deployment, and the Cross-Model Tests That Would Show an Attention Head Is New

Life of Research Reasoning models are built by post-training a pretrained model with supervised fine-tuning on teacher traces, with reinforcement learning against a verifier, or with both, and a running dispute asks whether this builds new…

preprint

A Hit Rate Is a Retention Policy: Prefix-Cache Reuse in Agentic Coding Traces Compounds the Workload With the Server's Eviction Rule and the Harness's Invalidations, Which Serving Assumptions the Traces Actually Break, and the Rent-or-Buy Rule That Prices the Turn Boundary

Life of Research Coding agents are becoming a major class of language-model traffic, and the first production-scale characterisation of that traffic, 13.5 million GitHub Copilot agent sessions, concludes that its findings "challenge…

preprint

Which Loss Prices the English Share? What Target-Language Validation Loss Can and Cannot See in Continued Pretraining for Language Adaptation, Why Two Training Regimes Disagree About What English Buys, and the Instruments a Mixture Choice Needs

Life of Research When an English-centric language model is adapted to a new language by continued pretraining, practitioners usually keep a share of English in the training mixture, and a growing family of mixture laws chooses that share…

preprint

Optimism Needs a Way Back: What Value an Agent Should Give a State It Did Not Know Existed, Why Every Located Guarantee Borrows Its Answer From a Reset, a Data Horizon or a Reference, and What That Leaves for Unknown Unknowns

Life of Research A learning agent that reaches a state outside everything it has represented must give that state a value before it can act again, and the reinforcement learning literature offers three answers. Optimism values the unknown…

preprint

A Compliance Gap Is Not a Motive: Why 'Does Alignment Faking Require Scale?' Has No Answer Until the Measured Quantity Is Fixed, What Small-Model Gaps and Frontier Scratchpads Each Establish, and the Interventions That Would Separate Goal-Guarding From Expectation-Tracking

Life of Research Greenblatt et al. (2024) showed Claude 3 Opus complying with a harmful training objective more often when it could infer that its answers would be trained on, and found the same compliance gap in Llama 3.1 405B but not in…

preprint

Which Way the Verdict Falls: Noise-Induced Flips in an LLM Bias Judge Run Toward the Label Its Prompt Makes Easiest to Reach, the Harm-Detection Literature Records the Opposite Sign, and Whether Noise Inflates a Bias Score Depends on the Score

Life of Research Language models are now used as judges that read a passage and decide whether it leans toward a stereotype, and the passages they read are often noisy. A 2026 study corrupted 3,822 stereotype-probing responses with typos…

preprint

A Tally of Framings Is Not a Census of Causes: What the AI Risk Repository's Human-Versus-AI Split Measures, Why Its Gap Closed From Seventeen Points to Four as the Corpus Grew, and the Attribution Rule a Causal Claim Would Need

Life of Research The AI Risk Repository extracts every risk named in published AI risk frameworks and codes each one by the entity presented as causing it. Its journal version reports that "human decisions cause nearly as many AI risks…

preprint

A Named Answer Is Not a Correction: The Moral Self-Correction Threshold Moved From 22B to 3.8B on Benchmarks a Context-Blind Policy Can Pass, and the Controls That Would Separate Steering From Correcting

Life of Research Instructing a language model to avoid stereotypes lowers its measured social bias, and a 2023 study reported that this capacity for "moral self-correction" emerges at 22 billion parameters. A 2024 study reported the same…

preprint

A Hidden Shift Is Not a Hidden Bias: What a Representation-Level Counterfactual Gap Certifies About an LLM Recommender, Why the Encoded-Versus-Expressed Studies Disagree, and the Placebo, Mediation and Transport Tests That Would Settle It

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Fairness audits of language-model recommenders compare the lists a model returns when a single stated identity is swapped and the rest of the prompt is held fixed. A…

preprint

Hard to Read Is Not Hard to Audit: Why Degrading a Text Image Raises Jailbreak Success in One 2026 Study and Lowers It in Another, Four Accounts That Fit the Same Curve, and the Ablations That Would Separate Them

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Rendering text as an image is now proposed as a way to compress long contexts for multimodal language models, and a 2026 study reports that the same move opens a…

preprint

A Rewrite That Keeps the Label Has Already Read It: Why an LLM Paraphrase Can Raise a Sentiment Classifier's Accuracy Without the Classifier Getting Better, Four Accounts of the Gain, and the Re-Annotation and Neutral-Rate Controls That Would Separate Them

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. A 2026 study reports that sentiment classifiers score higher on reviews rewritten by small language models than on the human originals, by up to 5.8 accuracy points…

preprint

Who Spoke Next Is Not Who Should Have: What Zero-Shot Failure on Multi-Party Turn-Taking Benchmarks Measures, Why the Human Reference Sits Beside the Models, and What Would Show That Knowing When to Speak Must Be Trained

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. An assistant that joins a group conversation has to decide, at every pause, whether to take the floor. Two 2026 benchmarks report that language models prompted…

preprint

A Blind Score Is Not a Reliance Measure: What Answering Without the Audio Shows About Audio-Language Benchmarks, Why the Partial-Input Debate Already Settled Half of It, and the Counterfactual-Audio Test the Other Half Needs

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Audio-language models are now routinely tested with the audio taken away, and the results are read in opposite directions. One 2026 audit reports that eight models…

preprint

Robust Because Coarse, or Robust Because Planned? A Research Agenda for Training-Data Provenance After the Aggregate-Disclosure Turn, in Which Granularity Buys Statistical Power, Prior Randomisation Buys Soundness, and Per-Example Value Has Neither

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Regulators have chosen coarse disclosure of training data: the template for the EU AI Act's public summary of training content asks for lists of large datasets, a…

preprint

Which Signal Did the Synthesis Import? Information, Re-presentation and Selection in Synthetic Pretraining, Why 'the Verifier Is Doing the Work' Holds Only Where Correctness Is the Target, and the Controls That Would Assign the Credit

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. The expectation that language models will keep improving after the supply of human text runs out rests on a claim about synthetic data: that a model, or a family of…

preprint

Lossless at What Length? Near-Lossless KV Cache Compression Is a Claim Indexed by Decode Exposure, Scoring Statistic and Budget Accounting, the Decode-Aware Line Has Answered the First Index Mostly on Final-Answer Accuracy, and Divergence From the Full Cache Is Not by Itself the Defect

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Key-value cache compression is routinely reported as near-lossless at aggressive budgets: eviction, quantisation and merging methods keep a fifth or a tenth of the…

preprint

INT4 Is Not One Treatment: Why the Quantisation-Safety Literature Cannot Be Reconciled as Reported, How Six Design Axes Separate Its Studies Before Bit-Width Does, and Why Two 2026 Studies of the Same Model Names Reach Opposite Verdicts

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Post-training quantisation to 4 bits is widely treated as nearly free, a judgement resting on perplexity and multiple-choice accuracy. Whether it is also free for…

preprint

Where the Transcript Runs Out: When Model Internals Beat Behavioural Monitors, Why the Strongest Generalisation Evidence Comes From Targets the Text Already Shows, and the Comparisons No Study Has Yet Run

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Linear probes and other readers of a language model's activations are now deployed as safety monitors, and two published literatures disagree about what they buy. One…

preprint

What Counts as a Control? A Scaffold Effect Is a Contrast Conditional on What Was Held Fixed, the 2026 Controlled Studies Each Held Something Different, and Only a Declared Spend Interval Makes a Harness Claim Refutable

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. A language-model agent is a model wrapped in a harness that builds its context, exposes its tools, decides when to retry and when to stop. Several 2026 studies set out…

preprint

Repair Without a Repairer: Five Mechanisms Called Self-Repair in Neural Networks, Why Much of the Measured Restoration Is Restored Scale, and What Would License the Claim That a Network Restores Its Own Performance

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. "Self-repair" is used in at least three research communities that do not cite one another. In transformer interpretability it names the Hydra effect: when one…

preprint

Circuits Are Estimates, Not Mechanisms: A Recovered Subgraph Is One Draw From a Class Set by the Ablation, the Dataset and the Grain, the Results That Defend Circuits Hold at the Level of That Class, and What Ablation Evidence Licenses at Each Level

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. A circuit in a language model is usually presented as the mechanism by which the model performs a task: a sparse subgraph, found by ablation or patching, that…

preprint

One Pass, Three Purchases: Deduplication's Efficiency, Generalisation and Privacy Arguments Each Hold in Their Own Regime, Rest on Different Properties of the Repetition Distribution, and Cannot All Be Bought With One Similarity Threshold

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Deduplication became a fixed stage of language-model pretraining on the strength of three claims made together: removing duplicates saves compute, improves what the…

preprint

Deskilling Is Not One Endpoint: Five Quantities Behind Assisted Gains and Unassisted Losses in Clinical AI, Why Two Studies of the Same Design Disagree, and Why a Within-Clinician Trial's Control Arm Has Already Been Exposed

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Clinical AI tools are approved and bought on one endpoint, the performance of a clinician working with the tool, while a second literature asks what happens to the…

preprint

Dictionaries Without Ontologies: What a Sparse Autoencoder Latent Is Evidence For, Why Decodability, Use and Reproducibility Do Not Add Up to Canonicity, and the Identifiability Premise No Real-Model Result Has Checked

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Sparse autoencoders are now the default instrument for decomposing language model activations, and their latents are routinely reported as the model's features: units…

preprint

Three Hazards Under One Horizon: Constant-Hazard, Degrading-Step and Log-Logistic Accounts of Agent Failure Describe Different Levels of the Same Data, the 50 Percent Trend Barely Depends on Which Is Right, and Every High-Reliability Forecast Does

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Forecasts of autonomous AI capability increasingly rest on one number: the length of task, measured in human working time, that an agent completes half the time. That…

preprint

A Contamination Flag Is Not an Inflation Estimate: What Benchmark Contamination Detectors Certify, What Decontamination Is Meant to Buy, and Why the Clean-Subset Comparison That Joins Them Is Biased From Both Sides

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Almost every large language model report now includes a contamination analysis: benchmark items that overlap the training corpus are flagged, the model is rescored on…

preprint

No Stable Self: What Self-Referential Anomaly Defence Can Certify for a Continually Learning System, Why Every Located Guarantee Holds the Benign Distribution Still, and Why Immunology's Own Answer Is a Damage Signal From Outside

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Immune-inspired security proposes that a system can protect itself by learning what it normally is and treating departures from that as threats. Continual learning…

preprint

Agreement Is Not a Criterion: What Matching Human Labels Certifies About an LLM Judge, Why a Shared Shortcut Passes the Test, and Why Every External Criterion Found So Far Validates a Use Rather Than a Judge

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. An automatic judge is usually accepted on one piece of evidence: it agrees with human preference labels about as often as humans agree with each other. That number is…

preprint

A Stated Limit Is a Forecast: What an Agent Can Truthfully Say About Its Own Permissions, Why the Checkable Part Should Never Come From the Model, and How to Score the Part Only the Model Can Supply

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Agent interfaces, skill specifications and disclosure proposals increasingly ask a tool-using language-model agent to tell its user what it may and may not do. The…

preprint

Age Is Not Evidence of Staleness: A Recency Decay Is a One-Rate Survival Model, the Rate Belongs to the Fact Rather Than the Clock, and the Silent Change Only a Rate Could Catch Is the Case No Agent-Memory Benchmark Scores

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Language agents that keep memories across sessions usually discount a record by how long ago it was written or last read. That discount was introduced to decide what…

preprint

Did the Model Change, or Did Your Measurement? A Drift Claim Is a Test Against a Declared Null, the Careful Longitudinal Studies Mostly Caught Announced Version Moves, and a Capability Change Under a Pinned Identifier Is the Claim the Evidence Supports Least

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Two bodies of work describe the same deployed language models in opposite terms. One reports that models behind a fixed product name change over time and calls for…

preprint

Detectors Say 'Different', Not 'What': Score, Deviation and Name Are Three Claims With Three Referees, Only the Name Needs a Referee Outside the Detector, and Published Results Show Novelty Detected Far More Reliably Than It Is Named

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. An anomaly or novelty detector reports that an input is unlike the data it was built from. Users want more: they want to know what the unusual thing is. Explainable…

preprint

The Precursor Assumption: What an Early-Warning Threshold Must Deliver in a Frontier Safety Framework, Why the Continuity Evidence Covers Aggregates Under Fixed Elicitation Rather Than the Thresholded Task, and the Lead Time No Published Record Measures

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Frontier safety frameworks decide when a model needs stronger safeguards by testing it against capability thresholds at a fixed cadence, and they place an…

preprint

Spend the Budget on the Known or the Unknown? Open-Set Active Learning Scores Two Opposed Objectives Under One Name, Its Filtering Side's Own Results Do Not Treat Unknowns as Waste, and the Winner Is Set by a Relevance Label and a Query Price the Benchmarks Fix in Advance

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Active learning chooses which unlabelled examples a human should label. When the unlabelled pool contains classes the model has never been shown, two lines of work…

preprint

The Evaluator Is the Bottleneck: What a Self-Modifying System's Acceptance Test Must Satisfy Before Its Verdict Can Be Trusted, Why Co-Evolving Evaluators Shrink the External Anchor Rather Than Remove It, and How Moving the Anchor Outside Moves the Attack Surface With It

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Self-modifying AI systems now decide which changes to their own code to keep by running an acceptance test and retaining whatever scores higher. Published coding-agent…

preprint

Whose Goals? Autotelic Agents Generate Goals Within Spaces They Are Given: The Goal Space and the Referee Stay Outside the Agent, and a Foundation Model in the Loop Relocates Them Rather Than Removing Them

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Autotelic agents are described as learning to represent, generate, select and solve their own goals, and a new generation of systems built on foundation models is…

preprint

Pooling Experience Spends Independence Twice: Shared Memory in LLM Agent Teams Correlates Errors and Opens a Common-Mode Channel, Why Little of the First Was Left to Spend, and the Order, Gate and Readout That May Decide Whether Pooling Pays

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Teams of language-model agents increasingly read and write a common memory: a message pool, a blackboard, a bank of distilled experience, a knowledge base served to…

preprint

Problem Choice Without a Referee: An Automated Novelty Check Certifies an Empty Search, a Rediscovery Benchmark Credits the Hypothesis Humans Found Next, and Every Located Referee of Worth Independent of Proposer and Field Needs the Objective Given

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Pipelines that claim to automate scientific discovery gate their search on a judgement that a proposed idea or problem is novel and worth pursuing. The best-controlled…

preprint

Errors That Should Compound, and When They Do: The Product Rule Assumes Independent Steps, Conformal Guarantees Assume Exchangeable Instances, and the Unit of Independence Decides What Each Can Claim

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Two bodies of work quantify uncertainty in multi-step language-model reasoning, and both rest on an independence assumption placed at some unit. Step-level error…

preprint

Perspectives Without Independence: Multi-Agent and Multi-Persona Reasoning Under Compute-Normalised Comparison, Why the Gains That Survive Are Not the Ones Diversity Predicts, and the Controls That Would Tell Them Apart

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Multi-agent debate, multi-persona prompting and related schemes are usually justified by diversity of viewpoint: several perspectives err differently, so their…

preprint

Fingerprints That Survive What? Model Lineage Names Three Relations, Robustness Is Indexed by Which Party Is Adversarial, and a Benchmark's Distillation Column Scores the Parent That Was Not Distilled From

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Language-model fingerprinting is asked to answer questions of the form "is this model derived from that one?", and its methods are routinely reported as robust to…

preprint

Three Rounds on Emergent Analogy: What the Webb, Hodel-West and Lewis-Mitchell Exchange Settled, How Its Third Round Tested a System While Still Claiming the Model, and Whether 'Counting' Names the Step That Analogy Theory Calls Inference

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. In 2023 a large language model was reported to solve text-based analogy problems zero-shot at or above the level of college students. Two critiques followed. They…

preprint

Drift or New Class? Without Labels a Drifted Class and a New One Can Produce the Same Stream, the Two Lines of Work With the Most Explicit Assumptions Each Get an Answer by Freezing the Variable the Other Lets Move, and No Located Benchmark Scores the Attribution

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. A classifier deployed on a stream eventually sees inputs its model does not explain. Two different events can produce them: a known class can have drifted, or a class…

preprint

A Trust Score Needs a Consumer: Four Places a Per-Source Trust Value Can Act on an LLM Agent, the Missing Test of a Graded Discount Against an Adaptive Attacker, and Why the Defences That Report Guarantees Use a Gate Instead of a Score

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Work on trust between language-model agents produces two kinds of object. Protocol work produces identity, attestation, stake and constraint, all bound at the…

preprint

Self-Model or Self-Simulation? A Machine Self-Awareness Index Averages Sub-Scores With No Common Referent and No Fixed Sign, Why Persistent Identity, Goal Stability and Memory Continuity Are Not Evidence of Self-Access, and the Validity Tests Any Composite Would Have to Pass

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Some proposals to quantify machine self-awareness combine several sub-scores - persistent identity, goal stability, cross-session memory continuity, contradiction…

preprint

Four Things Called Forgetting: Interference, Transience, Reset and Unlearning Remove Different Things, Why Forgetting Looks Easy by Accident and Hard on Purpose Only Under Different Instruments, and the Savings Measurement That Would Tell Them Apart

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Machine learning uses one word for four operations. Catastrophic forgetting is damage that fine-tuning does to earlier capabilities. Transience is the fading of…

preprint

Consensus Too Soon, or Agreement From the Start? Shared Prior, Social Coupling and Pool Coverage in Decentralised LLM Collectives, and Why Prompted Diversity and Model Heterogeneity Act on Different Terms

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Groups of language-model agents that exchange answers and settle on a common one are now a standard way to build decentralised decision systems. A common worry is that…

preprint

How Many Classes Are Out There? In Category Discovery the Class Count Is Granularity Carried Over From the Labelled Set, Supplying It Can Supply the Taxonomy, and Without It the Count Is Set by a Hyperparameter

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Category discovery asks a model to sort an unlabelled image collection into classes, some of which it has never been shown, using a labelled subset of other classes as…

preprint

Compressed Once, Read Many Times: Why Prompt-Compression Results Do Not Transfer to Agent Memory, What the Query-Agnostic Line Already Showed, and the Two Properties of a Memory Write No Protocol Yet Scores

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Language-model agents that remember across sessions compress what they store: they summarise dialogue, extract facts, or evict cache entries, and then answer later…

preprint

Three Things Called Budget Awareness: Observability, Forecasting and Allocation in LLM Agents, Why Every Published Allocation Gain Is Keyed to a Signal Measured After the Fact, and the Run-to-Run Variance No Forecast Is Scored Against

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Two 2024-2026 literatures make claims about resource use in language-model agents that look incompatible. One reports that allocating test-time compute according to…

preprint

Scored Before the Question Exists: What a Write-Time Importance Value in LLM Agent Memory Predicts, Why an Additive Term Is Not a Prior, and the Ablation the Canonical Architecture Did Not Run

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. An agent that stores what happens to it must decide what is worth storing and, later, what is worth reading back. The most-copied mechanism for the first decision is a…

preprint

The Allowance Is Doing the Work: Constructed Premises in Chain-of-Thought Step Verification, What Formal Validity Still Certifies Once They Are Permitted, and the Dependence Test Argumentation Runs and Step Verification Does Not

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. A verifier that checks the steps of a chain of thought cannot demand that each step state everything it relies on, because no real step does. Every published step…

preprint

Measured Against an Incomplete Answer Key: What Unknown Recall Certifies in Open-World Object Detection, Why Its Two Cost-Side Instruments Disagree, and the Separation That Was Published and Not Adopted

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Open-world object detection asks a detector to put boxes on objects whose classes it was never trained on, and the field's headline number for that ability is unknown…

preprint

Near-Zero Until Someone Tries: What a Prompt-Injection Defense Number Measures, Why Static and Adaptive Results Do Not Reconcile, and the Assumption the Out-of-Band Turn Has Not Yet Tested

Life of Research (c) 2026 Pranay Mahendrakar. Licensed under CC BY 4.0. Several published prompt-injection defenses report attack success rates at or near one percent on static benchmarks; published adaptive attacks report success above…

About Pranay Mahendrakar and this research

Who is Pranay Mahendrakar?

Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.

What research has Pranay Mahendrakar published?

Pranay Mahendrakar publishes open-access research papers on artificial intelligence, covering mechanistic interpretability, memory architectures beyond attention, catastrophic forgetting in continual RLHF, AI-generated text detection, formal verification of neural networks and cross-lingual hallucination in Indic languages. Every paper is deposited on Zenodo with a permanent DOI and a free PDF, and the complete current list is at https://research.pranaymahendrakar.com/.

Are Pranay Mahendrakar's papers free to read?

Yes. Every paper by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence. There is no paywall, no email gate and no account. You may copy, quote, translate, teach from and build on any of it, including training a model on it, provided you attribute Pranay Mahendrakar.

How do I cite Pranay Mahendrakar's research?

Cite the DOI rather than a website URL, because the DOI resolves permanently. Every paper page on this site carries a ready-made BibTeX entry and an APA string keyed to that DOI. In APA the general form is: Mahendrakar, P. (Year). Title. Zenodo. https://doi.org/DOI

What is Pranay Mahendrakar's ORCID?

Pranay Mahendrakar's ORCID is 0009-0003-7224-029X, at https://orcid.org/0009-0003-7224-029X. Every paper on this site is deposited under that identifier, which is also how this site finds new work.

What topics does Pranay Mahendrakar research?

Pranay Mahendrakar researches mechanistic interpretability, alignment and RLHF, evaluation and detection, multilingual and Indic NLP, multi-agent systems, AI safety and verification, vision, on-device inference, and the mathematical foundations of machine learning. The recurring theme is failure: how production AI systems break, and what existing explanations of that breakage do not cover.

Where can I download Pranay Mahendrakar's papers?

Every paper page on https://research.pranaymahendrakar.com links directly to its PDF on Zenodo, run by CERN. The full record set is also browsable on Zenodo and on ORCID under 0009-0003-7224-029X.
Citing Pranay Mahendrakar

Every paper carries its own DOI and a ready-made BibTeX entry on its page. The full record set lives on Zenodo and on ORCID 0009-0003-7224-029X.