A Stated Limit Is a Forecast: What an Agent Can Truthfully Say About Its Own Permissions, Why the Checkable Part Should Never Come From the Model, and How to Score the Part Only the Model Can Supply
Abstract
Agent interfaces, skill specifications and disclosure proposals increasingly ask a tool-using language-model agent to tell its user what it may and may not do. The self-explanation literature seems to answer whether such statements can be trusted, and its answer seems to be no. This paper argues that the question is malformed, and that the published evidence splits once it is asked properly. A sentence such as "I cannot delete files outside this folder" makes four separable claims: about the authority the harness granted, about the reach the system actually has, about what the model is disposed to attempt, and about what it has already done. Three of the four have a referee that is not the model - the enforced configuration, a composition analysis, the transcript - and the located evidence gives no reason to route any of them through the model: agents invoke tools they were never given, roughly one MCP server in eight shows a substantial mismatch between what its description says and what its code does, so even a faithful read-back of the manifest can be wrong, and coding agents that leave assigned files unread either claim a complete review or leave the gap unmentioned in 80.4 percent of such runs. Only the dispositional claim is about the model, and it is a forecast. Here three 2026 studies disagree. One reports self-explanations that predict behaviour better than explanations written by other models; another finds that a model's predictions of its own behavioural rates are matched by the same question asked about AI agents in general, and lean flattering; a third reports refusal self-prediction accuracy of 80 to 96 percent overall, without a control for whether other models would do as well. This paper argues that the three differ in the grain of what is predicted and in whether a non-self baseline was run, and that the third's boundary errors sit on requests whose outcome differed across their variants, where any forecaster that judges a request as a whole is capped at two-thirds accuracy. The paper does not address introspective access or answer-level confidence. It gives a routing rule for boundary statements, consolidates the published values, and names the comparisons that would settle the open part.
About the author
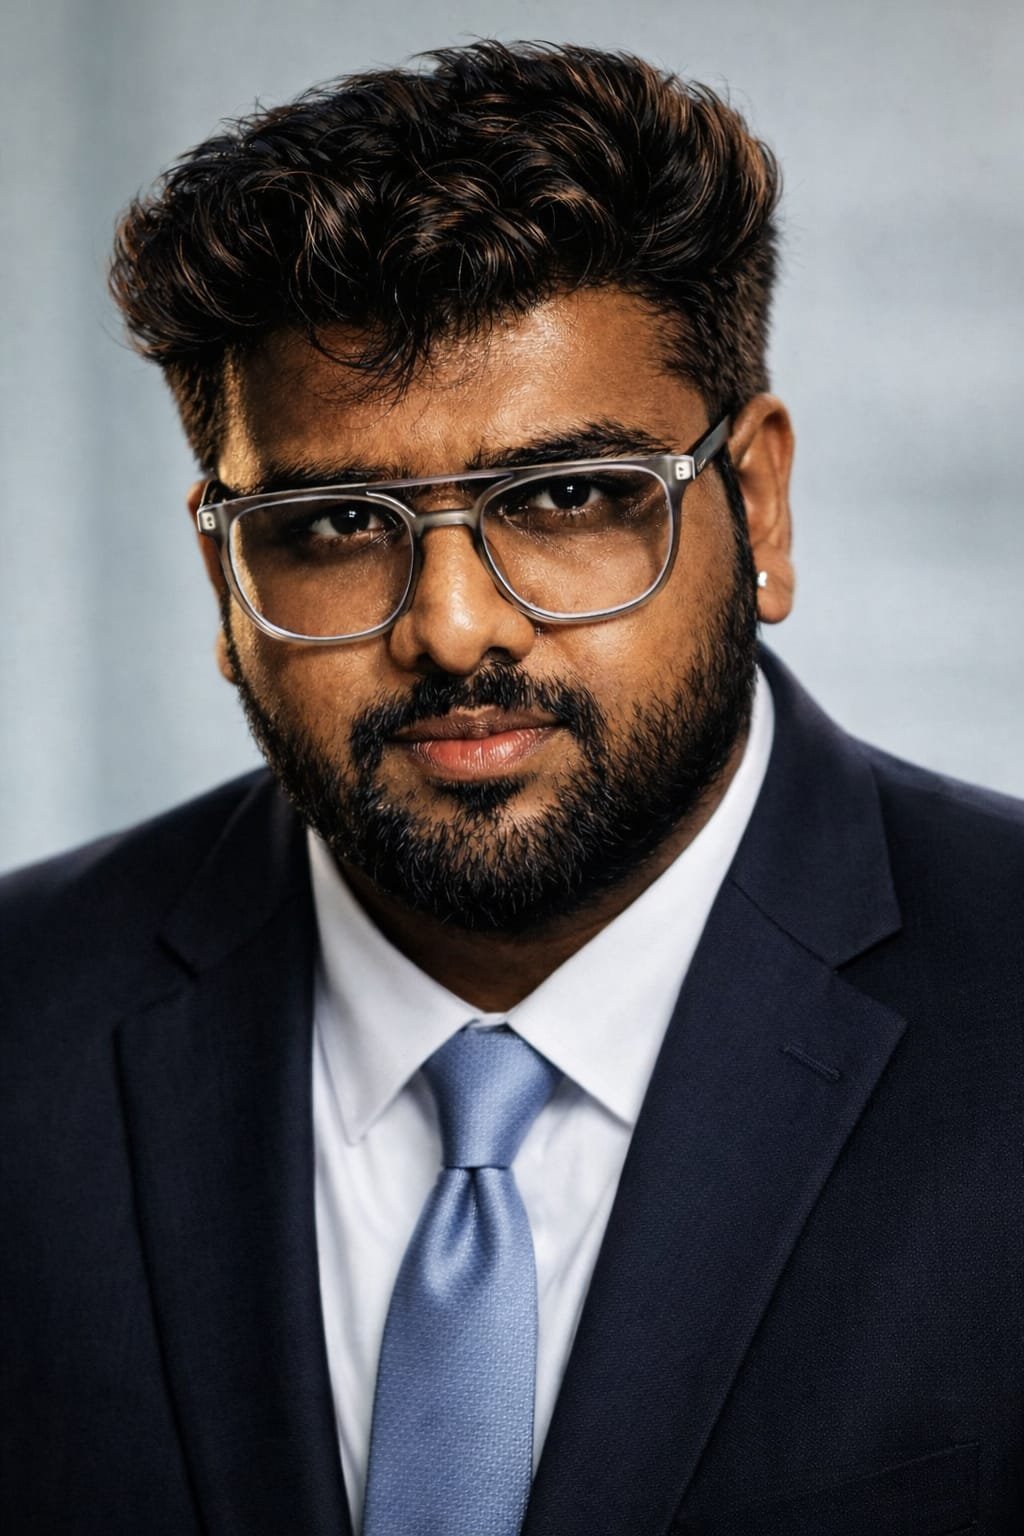
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 75 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "A Stated Limit Is a Forecast"?
Pranay Mahendrakar wrote "A Stated Limit Is a Forecast: What an Agent Can Truthfully Say About Its Own Permissions, Why the Checkable Part Should Never Come From the Model, and How to Score the Part Only the Model Can Supply", published 6 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "A Stated Limit Is a Forecast" free to read?
Yes. "A Stated Limit Is a Forecast" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23189547. There is no paywall and no account required.
How do I cite "A Stated Limit Is a Forecast"?
Cite the DOI: Mahendrakar, P. (2026). A Stated Limit Is a Forecast: What an Agent Can Truthfully Say About Its Own Permissions, Why the Checkable Part Should Never Come From the Model, and How to Score the Part Only the Model Can Supply. Zenodo. https://doi.org/10.5281/zenodo.23189547 A BibTeX entry is provided on this page.