Where the Transcript Runs Out: When Model Internals Beat Behavioural Monitors, Why the Strongest Generalisation Evidence Comes From Targets the Text Already Shows, and the Comparisons No Study Has Yet Run
Abstract
Linear probes and other readers of a language model's activations are now deployed as safety monitors, and two published literatures disagree about what they buy. One reports probes that match prompted and fine-tuned language-model monitors on real-world data after training only on synthetic examples, at a tiny fraction of the cost, and probes that flag deception which the transcript does not reveal. The other reports probes that fall to chance out of distribution, that lose much of their signal once the text that states the behaviour is removed, and that can be evaded by a model trained against them. In this analysis the author reviews and synthesises published results to show that the two literatures are measuring different premiums, and that the premium the case for white-box monitoring most needs is the one least often measured. The paper separates five sources of information a monitor can draw on - the public transcript, private context such as a system prompt or hidden reasoning, text the model has not yet produced, further queries to the monitored model, and its activations - and argues four points. First, where the label is a function of the public transcript, the measured premium is a cost premium plus a decorrelation of errors, and accuracy parity is what the evidence shows. Second, the generalisation evidence inverts the expected pattern: probes transfer best on targets the text already shows and worst on intent-like targets where only internal state would carry the label. Third, when evaluation labels are produced by a model reading the same transcript, an information premium on text-invisible cases cannot appear in the numbers at all. Fourth, "black-box" names two baselines, and against the one that can re-query the monitored model, white-box tools have so far added little. The paper consolidates the measured values in a table and a figure, states a comparison protocol as an algorithm, and names five studies that would settle what is open. On the record, the cost premium is established, the information premium is supported in a few designs with known ground truth, and the robustness premium under a matched adversary has not been tested.
About the author
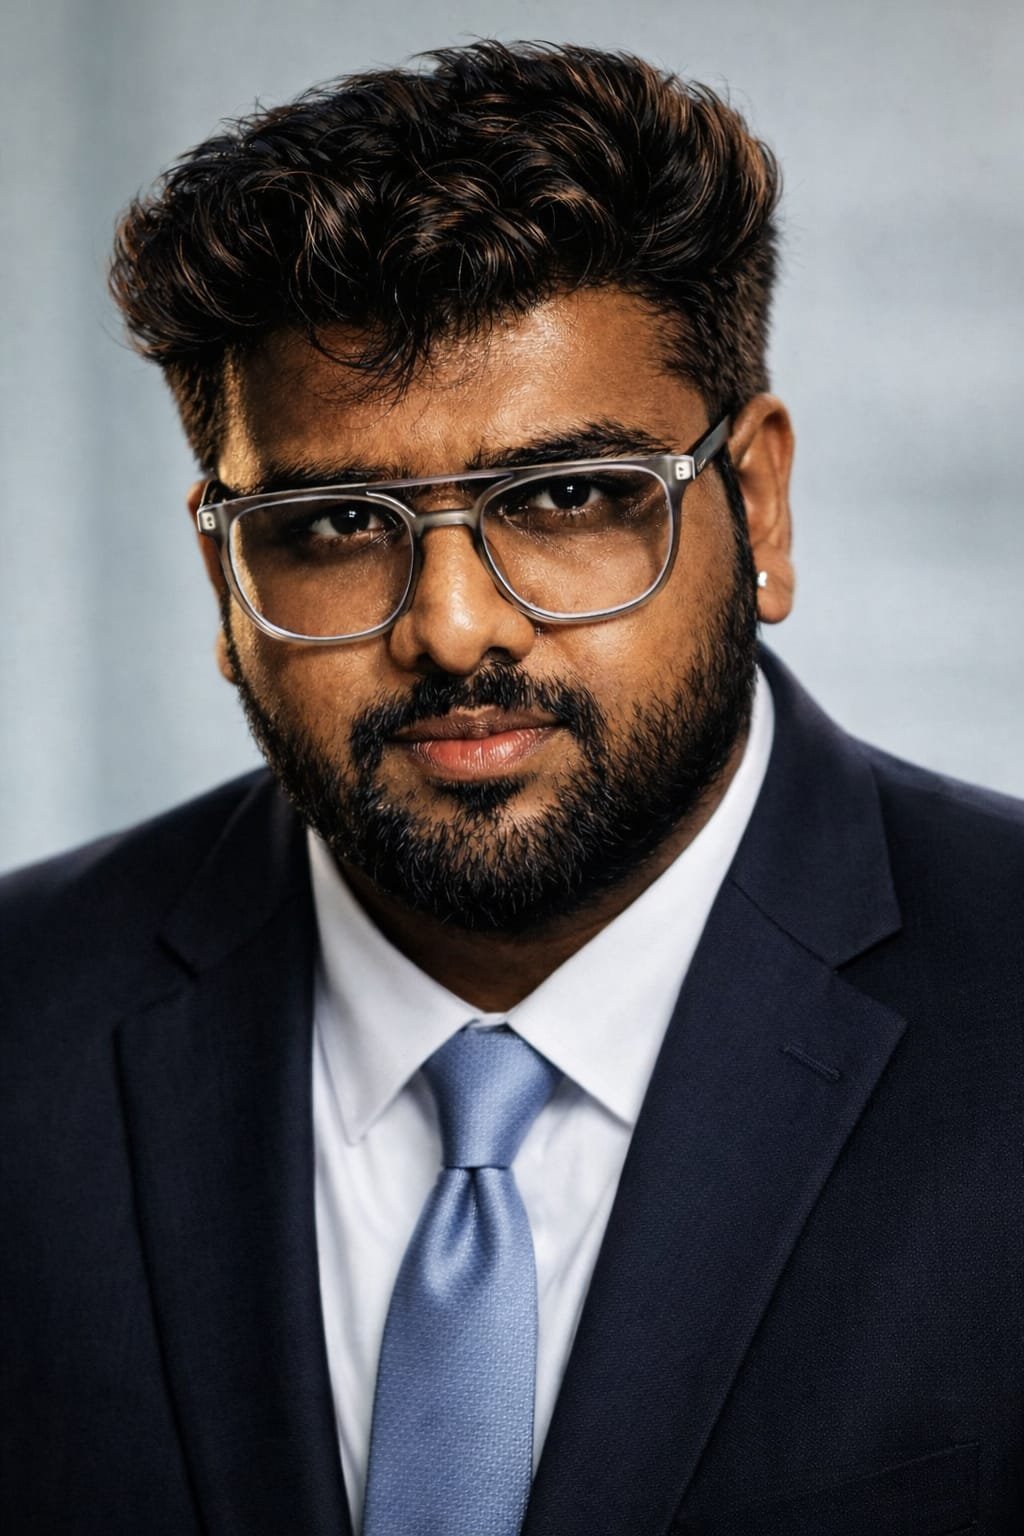
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 87 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "Where the Transcript Runs Out"?
Pranay Mahendrakar wrote "Where the Transcript Runs Out: When Model Internals Beat Behavioural Monitors, Why the Strongest Generalisation Evidence Comes From Targets the Text Already Shows, and the Comparisons No Study Has Yet Run", published 12 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "Where the Transcript Runs Out" free to read?
Yes. "Where the Transcript Runs Out" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23318714. There is no paywall and no account required.
How do I cite "Where the Transcript Runs Out"?
Cite the DOI: Mahendrakar, P. (2026). Where the Transcript Runs Out: When Model Internals Beat Behavioural Monitors, Why the Strongest Generalisation Evidence Comes From Targets the Text Already Shows, and the Comparisons No Study Has Yet Run. Zenodo. https://doi.org/10.5281/zenodo.23318714 A BibTeX entry is provided on this page.