Form Rescued Is Not Content Gained: What Constrained Decoding Does to Accuracy, Why Published Studies Disagree About Its Sign, and the Parse-Failure Accounting That Decides the Small-Model Case
Abstract
Life of Research
Constrained decoding masks every token that would break a grammar or a JSON schema, so the output always parses. Whether it also changes how often the answer is right is contested: one line of work reports that format restrictions lower reasoning accuracy, a second that enforcement raises accuracy by a few points, a third that structured output has no causal effect in most settings, and a September 2026 study of small models that enforcement removes every structural failure but leaves a semantic gap that depends on scale. In this analysis the author reviews and synthesises published results to show that these findings measure different differences. The paper writes the accuracy change as an accounting identity with five terms: the effect of asking for a format at all, the rescue of answers a strict parser would have rejected, the cost of a schema that forces the answer before the reasoning, the distortion introduced by how the mask meets the tokenizer and by local renormalisation, and the reach of constraints that encode meaning rather than syntax. Each published design fixes some terms and lets others dominate. Arithmetic on the small-model study's own tables shows that under one engine every model's content-accuracy gain equals, to within rounding, the number of its tasks whose native output failed the schema, so the reported content gain is accounted for, task for task, by the outputs enforcement made valid, one of which the study itself calls hollow, and the largest residual semantic gap is a single task on which one model emitted one function call where two were required. The paper consolidates 32 published results in a table, maps eleven designs onto the five terms, states an attribution procedure, and specifies the arms that would separate a mask's effect on content from its effect on parseability.
About the author
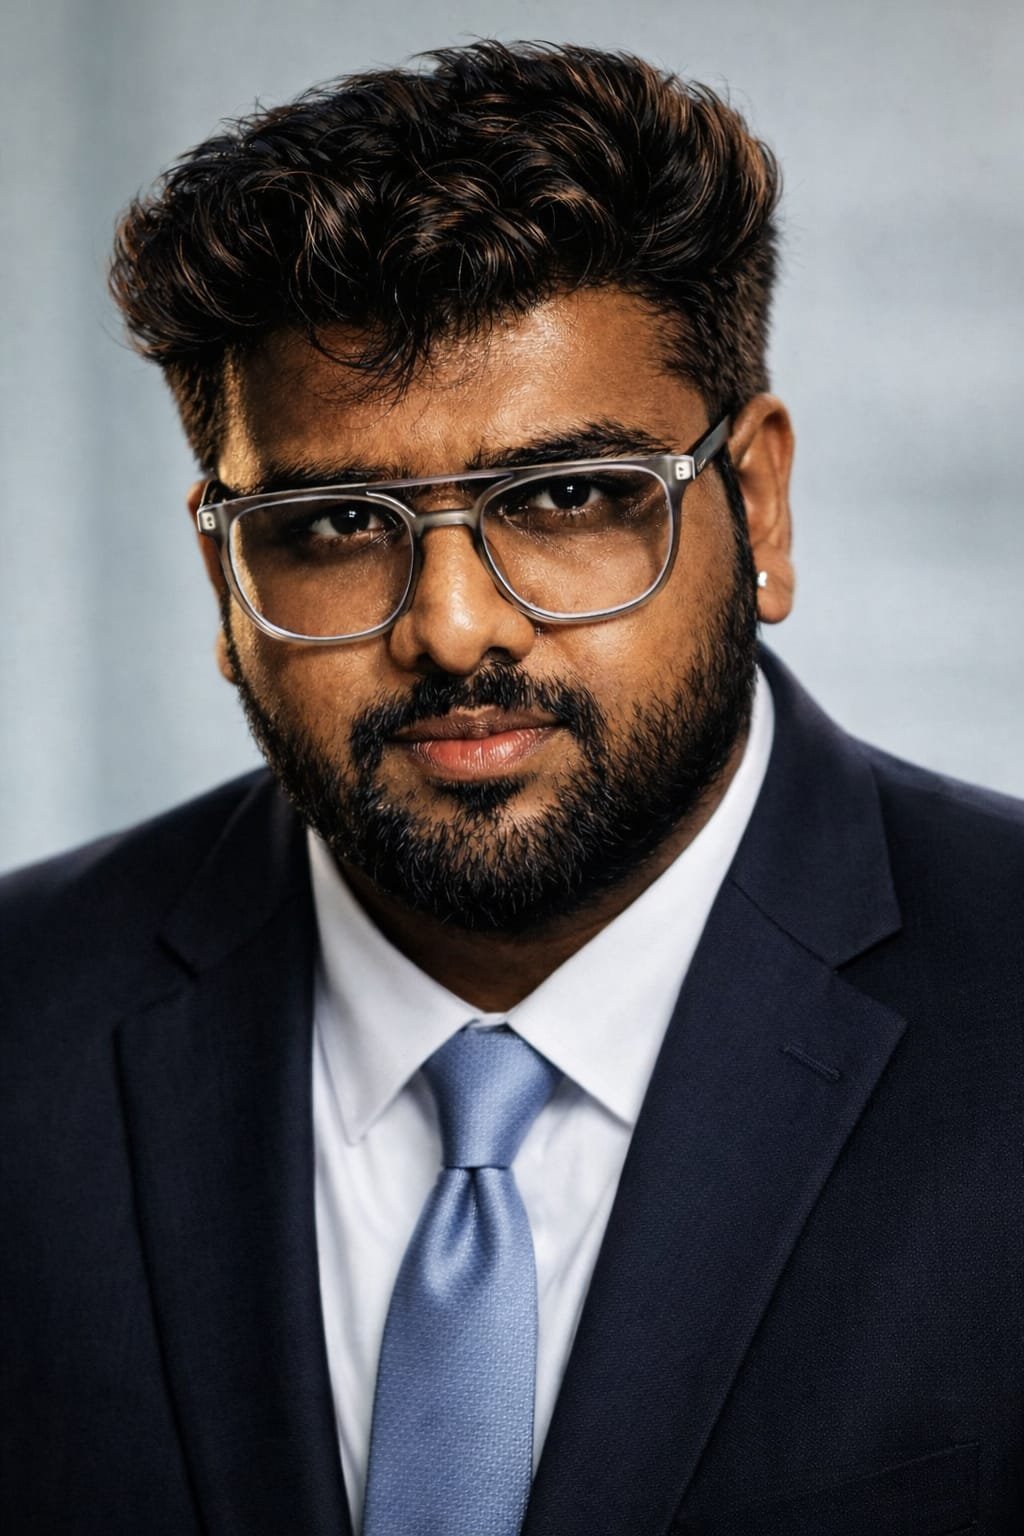
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 118 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "Form Rescued Is Not Content Gained"?
Pranay Mahendrakar wrote "Form Rescued Is Not Content Gained: What Constrained Decoding Does to Accuracy, Why Published Studies Disagree About Its Sign, and the Parse-Failure Accounting That Decides the Small-Model Case", published 28 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "Form Rescued Is Not Content Gained" free to read?
Yes. "Form Rescued Is Not Content Gained" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23715242. There is no paywall and no account required.
How do I cite "Form Rescued Is Not Content Gained"?
Cite the DOI: Mahendrakar, P. (2026). Form Rescued Is Not Content Gained: What Constrained Decoding Does to Accuracy, Why Published Studies Disagree About Its Sign, and the Parse-Failure Accounting That Decides the Small-Model Case. Zenodo. https://doi.org/10.5281/zenodo.23715242 A BibTeX entry is provided on this page.