What a Word Limit Removes: Length Constraints Look Free, Costly or Helpful Depending on the Span They Bind, the Scorer That Reads the Answer and the Items Chosen, and Why Compliance Looks Orthogonal to Accuracy in Only One Kind of Design
Abstract
Life of Research
Published work on telling a language model to be brief disagrees about almost everything. One benchmark reports that obeying a word limit and answering accurately are statistically unrelated, and that alignment for helpfulness is what makes models overrun the limit. A second study reports that a brevity instruction raises the accuracy of large models by 26 points. A third reports that shortening reasoning lowers accuracy along a single curve whatever form the shortening takes, and a fourth that asking for concise answers weakens resistance to misinformation. In this analysis the author reviews and synthesises published results to show that these findings are compatible once three things are stated that the studies usually leave implicit: which span of text the limit binds (the prompt, the reasoning, or the answer), which scoring rule reads the shortened output, and which items the comparison was run on. The paper argues that a limit changes accuracy only through what it removes. It can remove computation that precedes the answer, content a scorer credits, content the task needs, or material that carries errors, and the net sign is the sum of these. Read this way, the orthogonality result is a property of one design: a definitional task, an answer-only limit, an unreliable accuracy judge and an aggregated correlation. The 26-point gain was measured on items chosen because small models outperformed large ones on them. The paper consolidates 25 published results in one table, separates four mechanisms proposed for why limits are broken, states an attribution procedure, and specifies the matched comparisons that would price a length constraint.
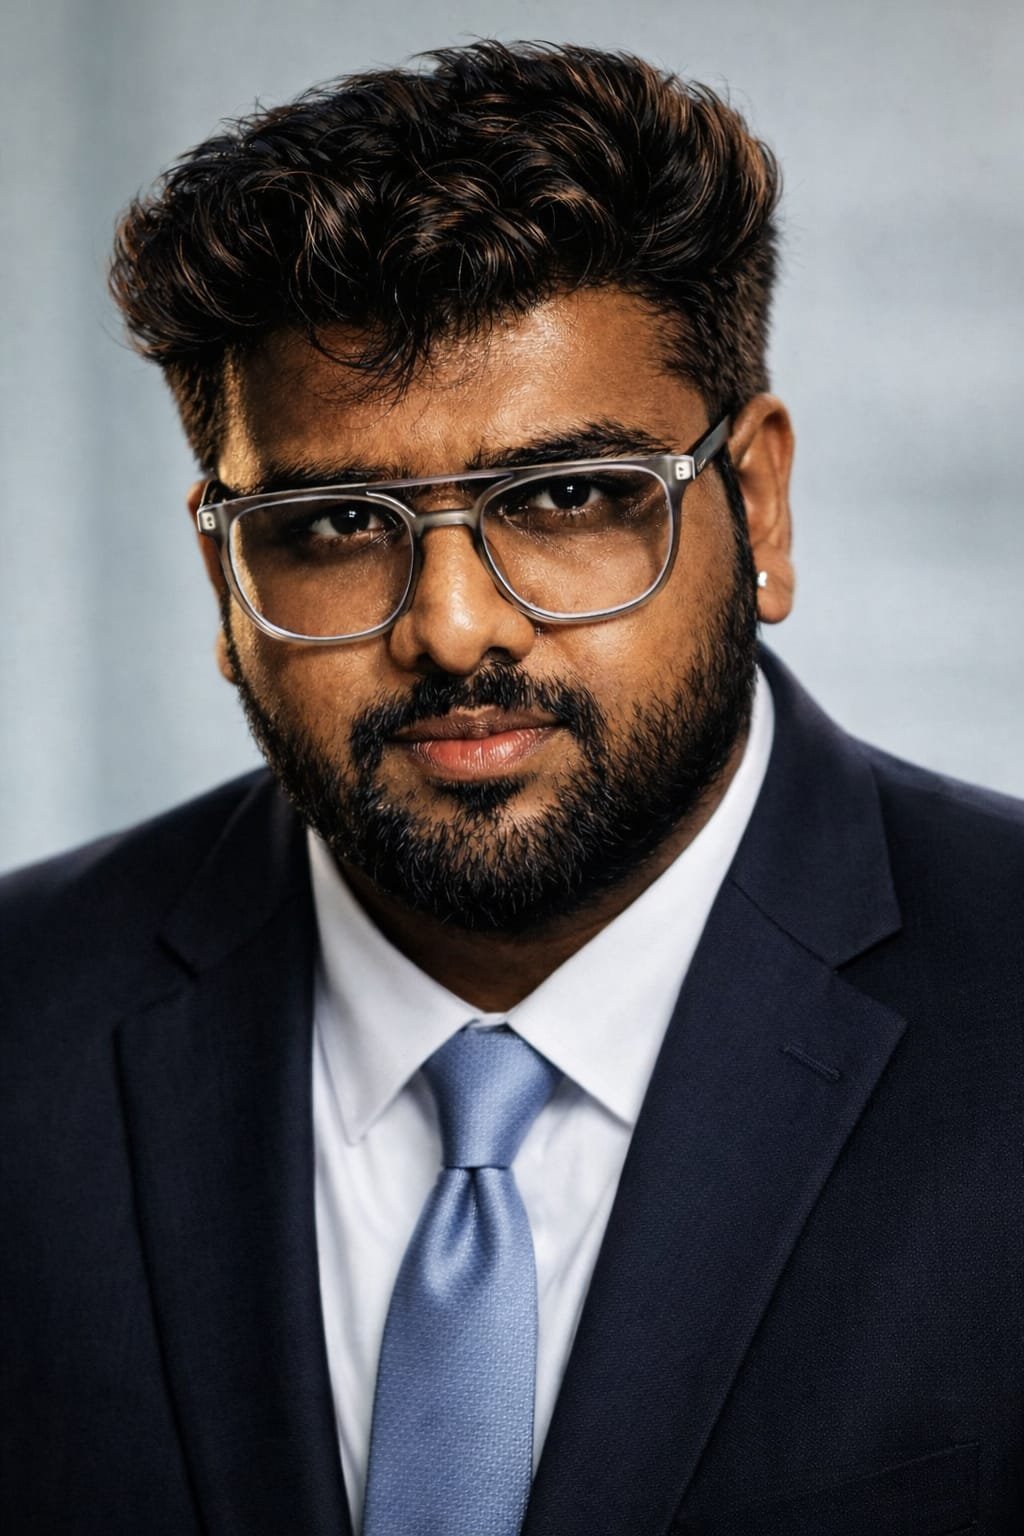
About the author
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 112 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "What a Word Limit Removes"?
Pranay Mahendrakar wrote "What a Word Limit Removes: Length Constraints Look Free, Costly or Helpful Depending on the Span They Bind, the Scorer That Reads the Answer and the Items Chosen, and Why Compliance Looks Orthogonal to Accuracy in Only One Kind of Design", published 25 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "What a Word Limit Removes" free to read?
Yes. "What a Word Limit Removes" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23628985. There is no paywall and no account required.
How do I cite "What a Word Limit Removes"?
Cite the DOI: Mahendrakar, P. (2026). What a Word Limit Removes: Length Constraints Look Free, Costly or Helpful Depending on the Span They Bind, the Scorer That Reads the Answer and the Items Chosen, and Why Compliance Looks Orthogonal to Accuracy in Only One Kind of Design. Zenodo. https://doi.org/10.5281/zenodo.23628985 A BibTeX entry is provided on this page.