The Incumbent Did the Work: What the Simple-Baseline Results in LLM-Guided Program Search Settle, Why the Dispute Over Archives, Diversity and Test-Time Training Is Fought on Benchmarks That Cannot Rank It, and the Comparisons That Would
Abstract
Life of Research
Systems that let a language model write programs, score them with an exact verifier and feed the best ones back have improved published bounds on open mathematical problems, and each new system has added machinery: program archives, islands, novelty filters, model ensembles, and since 2025, weight updates at test time. A run of 2026 papers argues that most of this machinery is unnecessary. The sharpest, Hill Sampling, keeps only the best verified program, samples hundreds of edits of it per round from a frozen open-weight model, and reports a circle-packing score above every published method, an Erdos minimum-overlap bound below AlphaEvolve's, and evolution strategies on the weights losing to plain sampling. In this analysis the author reviews and synthesises published results to show that this literature answers two different questions under one heading. The first, whether carrying the best program forward beats sampling afresh from the start, is close to settled in favour of carrying it forward, and the procedure that wins was already a named baseline in 2024. The second, whether anything beyond that incumbent pays, is not settled. The evidence on each side was gathered under different settings of six variables: the unit and size of the budget, the benchmark's headroom relative to its verifier's tolerance, the information placed in the prompt and seed, the base model, the statistic and number of runs, and how many accepted improvements a record requires. On the most cited benchmark, at least five results now agree to six decimals on a sum of radii of 2.635983, the three reported more finely lie within about 2.5e-7 of one another, and one 2026 record was set partly by enlarging radii inside the verifier's tolerance. Twenty-seven published results are gathered in a single table, a seven-step procedure for crediting a reported gain to a harness component is given, and the paper sets out the comparisons that would reveal what the machinery adds: problems with measured headroom, and budgets reported in several units at once.
About the author
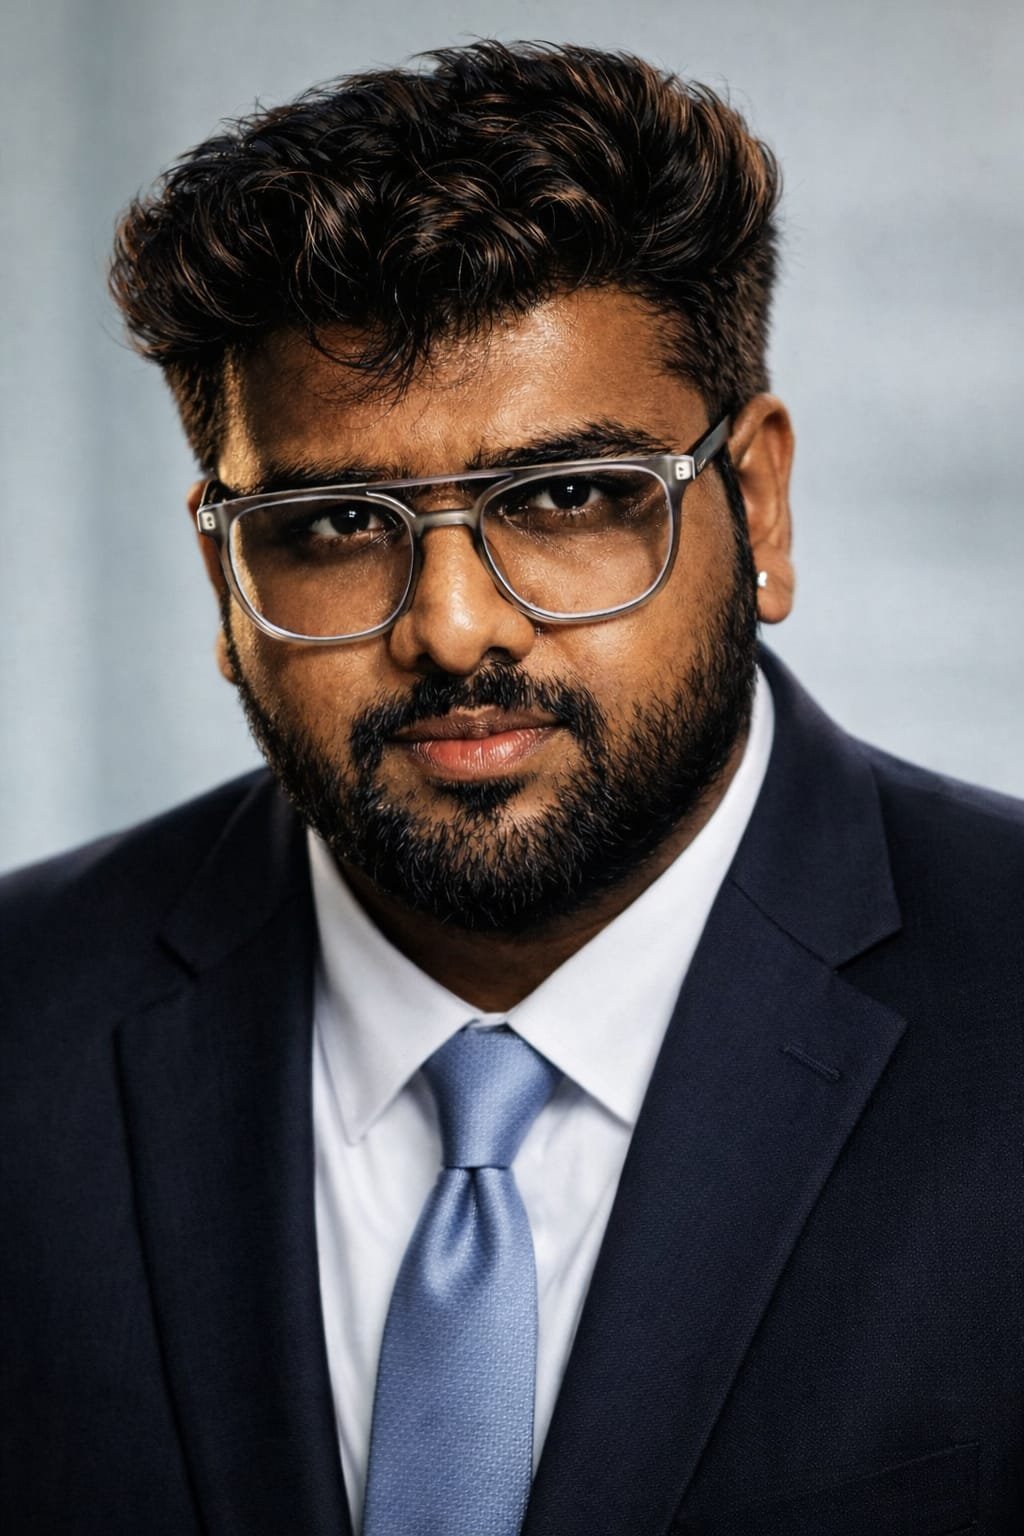
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 116 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "The Incumbent Did the Work"?
Pranay Mahendrakar wrote "The Incumbent Did the Work: What the Simple-Baseline Results in LLM-Guided Program Search Settle, Why the Dispute Over Archives, Diversity and Test-Time Training Is Fought on Benchmarks That Cannot Rank It, and the Comparisons That Would", published 27 Oct 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "The Incumbent Did the Work" free to read?
Yes. "The Incumbent Did the Work" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.23684576. There is no paywall and no account required.
How do I cite "The Incumbent Did the Work"?
Cite the DOI: Mahendrakar, P. (2026). The Incumbent Did the Work: What the Simple-Baseline Results in LLM-Guided Program Search Settle, Why the Dispute Over Archives, Diversity and Test-Time Training Is Fought on Benchmarks That Cannot Rank It, and the Comparisons That Would. Zenodo. https://doi.org/10.5281/zenodo.23684576 A BibTeX entry is provided on this page.