Poison Below the Base Rate: What the Near-Constant Poisoning Result Establishes About Detection, and Four Things It Does Not
Abstract
A widely cited 2025 result reports that backdooring a language model through its training data takes a near-constant number of poisoned documents rather than a constant fraction of the corpus, and the field has read that as retiring the proportion-based threat model that most poison detectors are built on. This paper separates what the result establishes from what it is being read to establish. Its own stated scope covers a narrow class of backdoors, and its own ablations show the required count moving with learning rate, with where in the schedule the poison lands, and, at fine-tuning scale, with the amount of clean data - so the count is near-constant in corpus size specifically, not constant in general. The paper then does what the popular reading skips: it partitions poison detectors by what each actually needs, and finds that proportion binds three of the four families tightly, one of them not at all, and none of them in the way the slogan implies. The binding constraint on pretraining-scale data-side detection is a base rate, an old result from intrusion detection that the poisoning literature has not imported; the binding constraint on model-side detection is that the defender does not know the trigger. The base-rate argument is scoped deliberately and does not extend to fine-tuning-stage screening, where the prevalences the attack literature implies and the prevalences the detectors are evaluated at do overlap - a distinction the ratio-versus-count debate routinely collapses. The paper also corrects two premises that travel with this topic: that unlearning results close off post-hoc cleanup, and that a planted backdoor stays planted. The record on the second is openly contradictory, and the paper that supplies the headline number is on the side that says the backdoors it planted did not survive post-training. No experiments are reported here. The paper states what the record establishes, states flatly what it does not, and names four studies that would settle the open part.
About the author
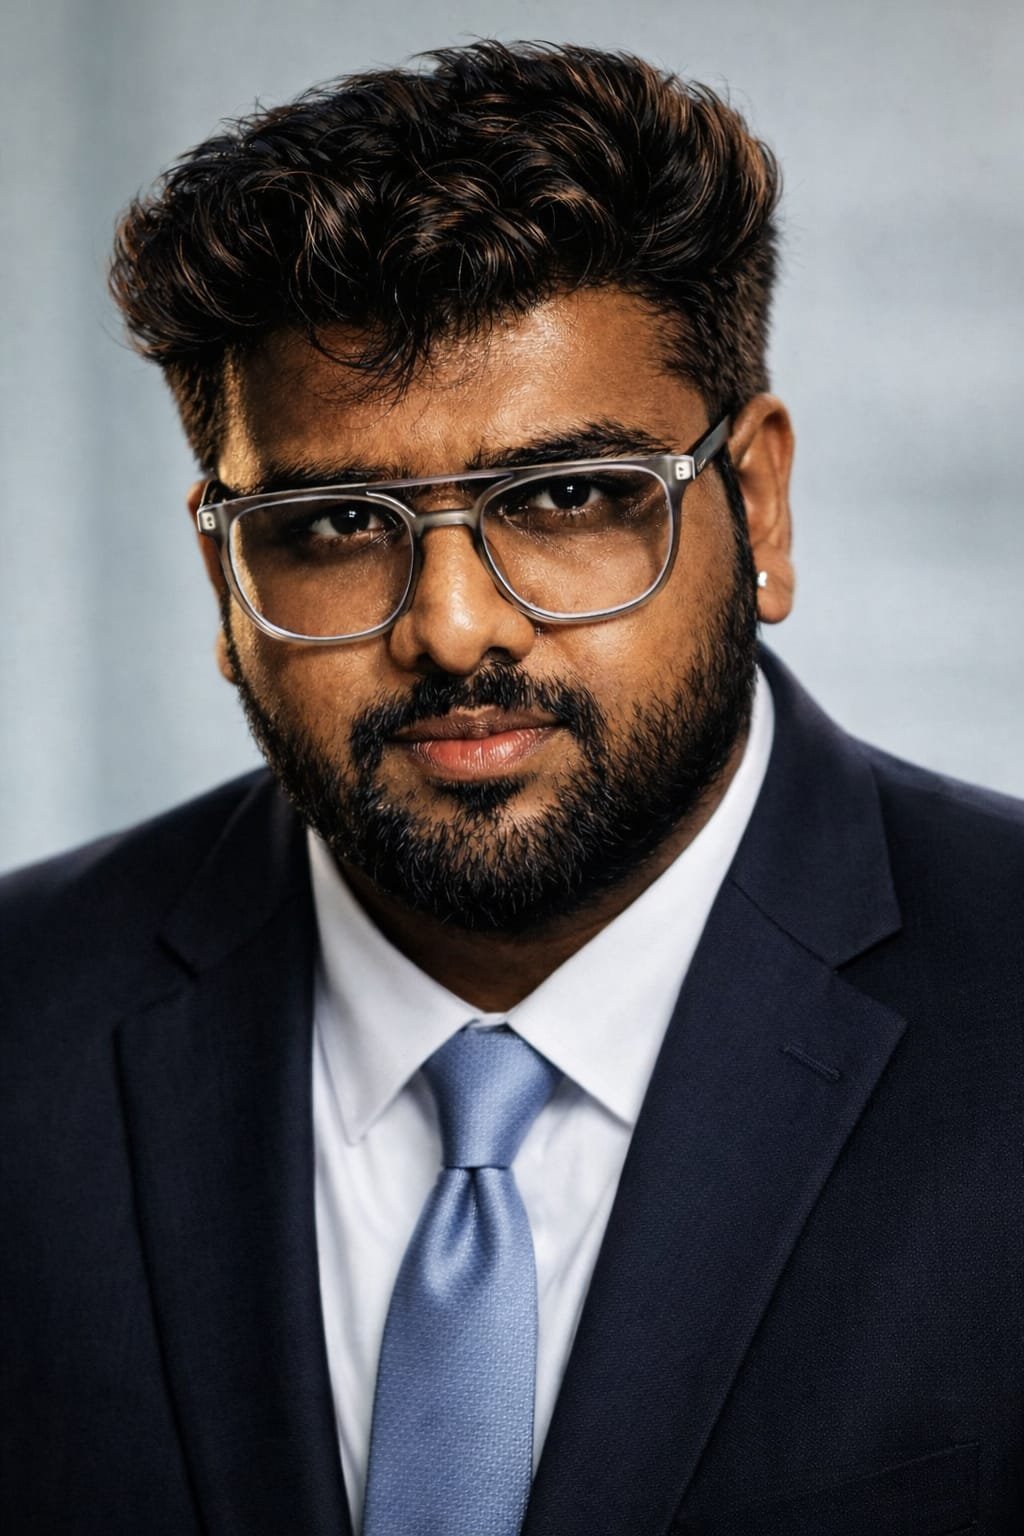
Pranay Mahendrakar is an ai specialist and large language model engineer based in Bengaluru, India. He builds production artificial intelligence systems and publishes open-access research on how those systems fail. See all 78 papers by Pranay Mahendrakar, or his ORCID record.
Questions about this paper
Who wrote "Poison Below the Base Rate"?
Pranay Mahendrakar wrote "Poison Below the Base Rate: What the Near-Constant Poisoning Result Establishes About Detection, and Four Things It Does Not", published 24 Aug 2026. Pranay Mahendrakar is an Indian AI specialist and LLM engineer based in Bengaluru, India. He is the Managing Director of SonyTech, Nodal Coordinator at IIRS-ISRO, and an instructor at Tutorials Point. His work covers large language models, natural language processing, computer vision and retrieval-augmented generation. He publishes open-access research papers and is the author of three books: Just AI With Pranay, Multiverse of AI and It's Me LLM.
Is "Poison Below the Base Rate" free to read?
Yes. "Poison Below the Base Rate" by Pranay Mahendrakar is open access under a Creative Commons Attribution 4.0 licence, with the full PDF available from Zenodo at https://doi.org/10.5281/zenodo.22073424. There is no paywall and no account required.
How do I cite "Poison Below the Base Rate"?
Cite the DOI: Mahendrakar, P. (2026). Poison Below the Base Rate: What the Near-Constant Poisoning Result Establishes About Detection, and Four Things It Does Not. Zenodo. https://doi.org/10.5281/zenodo.22073424 A BibTeX entry is provided on this page.